MatrAIxGitHub ↗Join us
Home / Research

The science of simulated users.

Questions, methods, and findings from the MatrAIx community—covering persona grounding, simulated users, interactive environments, evaluation, and identity drift.
Featured researchBrowse all research ↓

Research

PublicationOct 5, 2026
AgentPersonaBench: Benchmarking Persona-Driven User SimulationEvaluating whether latent persona profiles steer agent behavior across 2,460 tasks in surveys, chats, web, and desktop apps.
↗
Technical blogSep 15, 2026
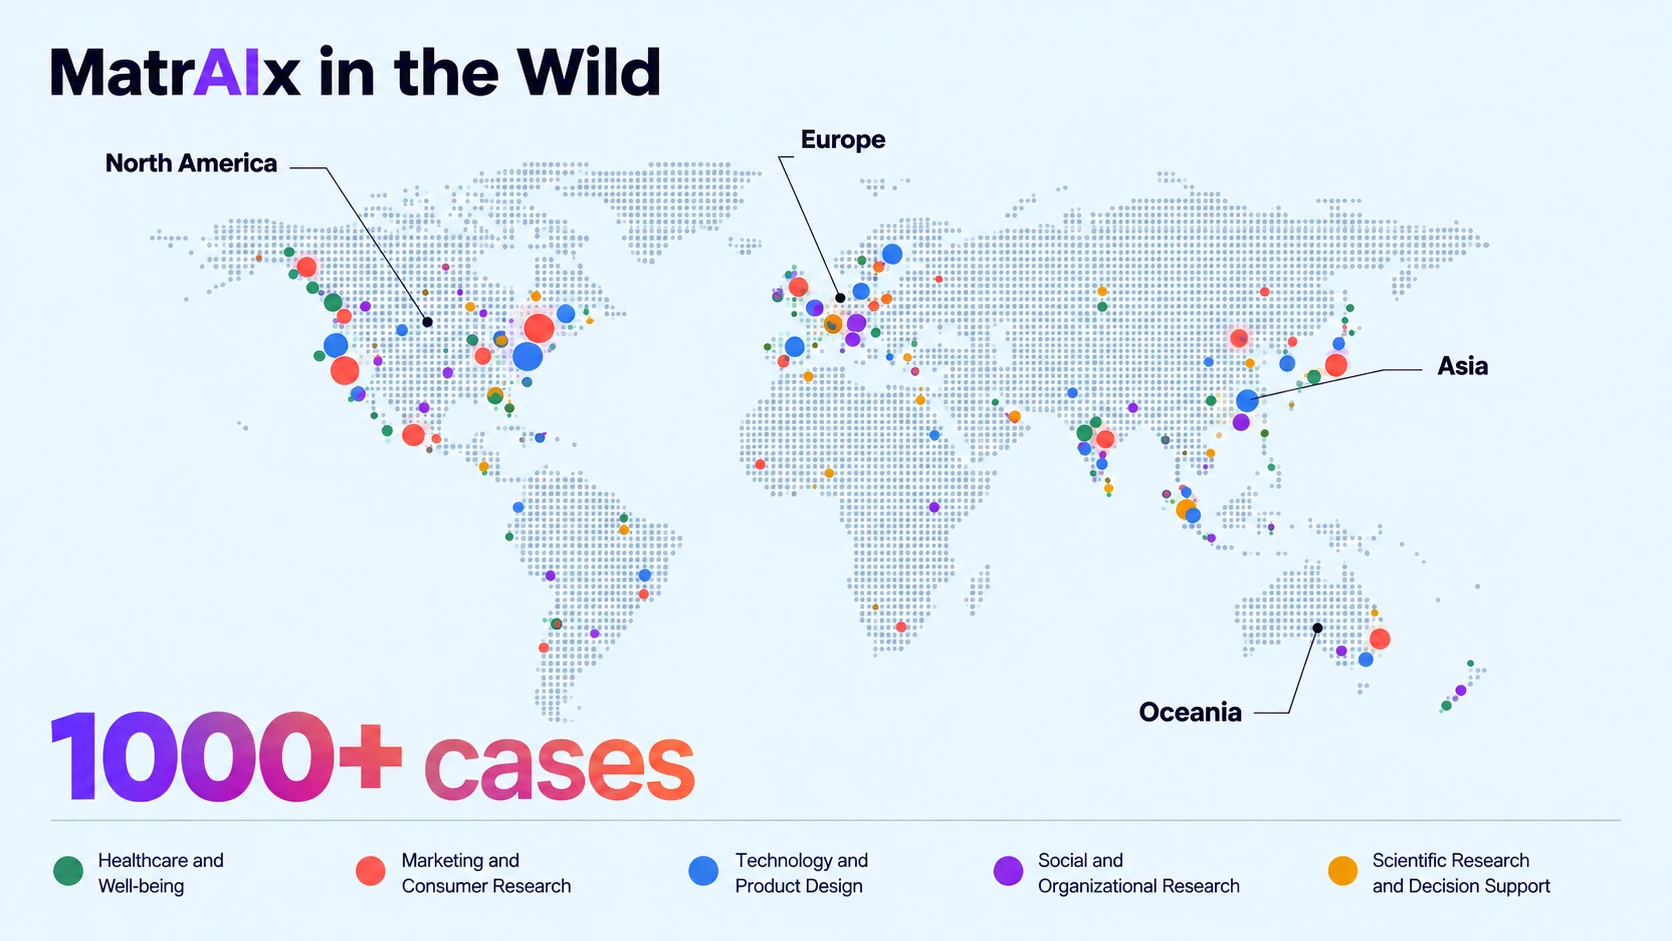
MatrAIx In The Wild: Technical BlogFrom real-world questions to actionable insights: how MatrAIx designs persona-based experiments and evaluates simulated results across different domains.
↗
PublicationAug 6, 2026
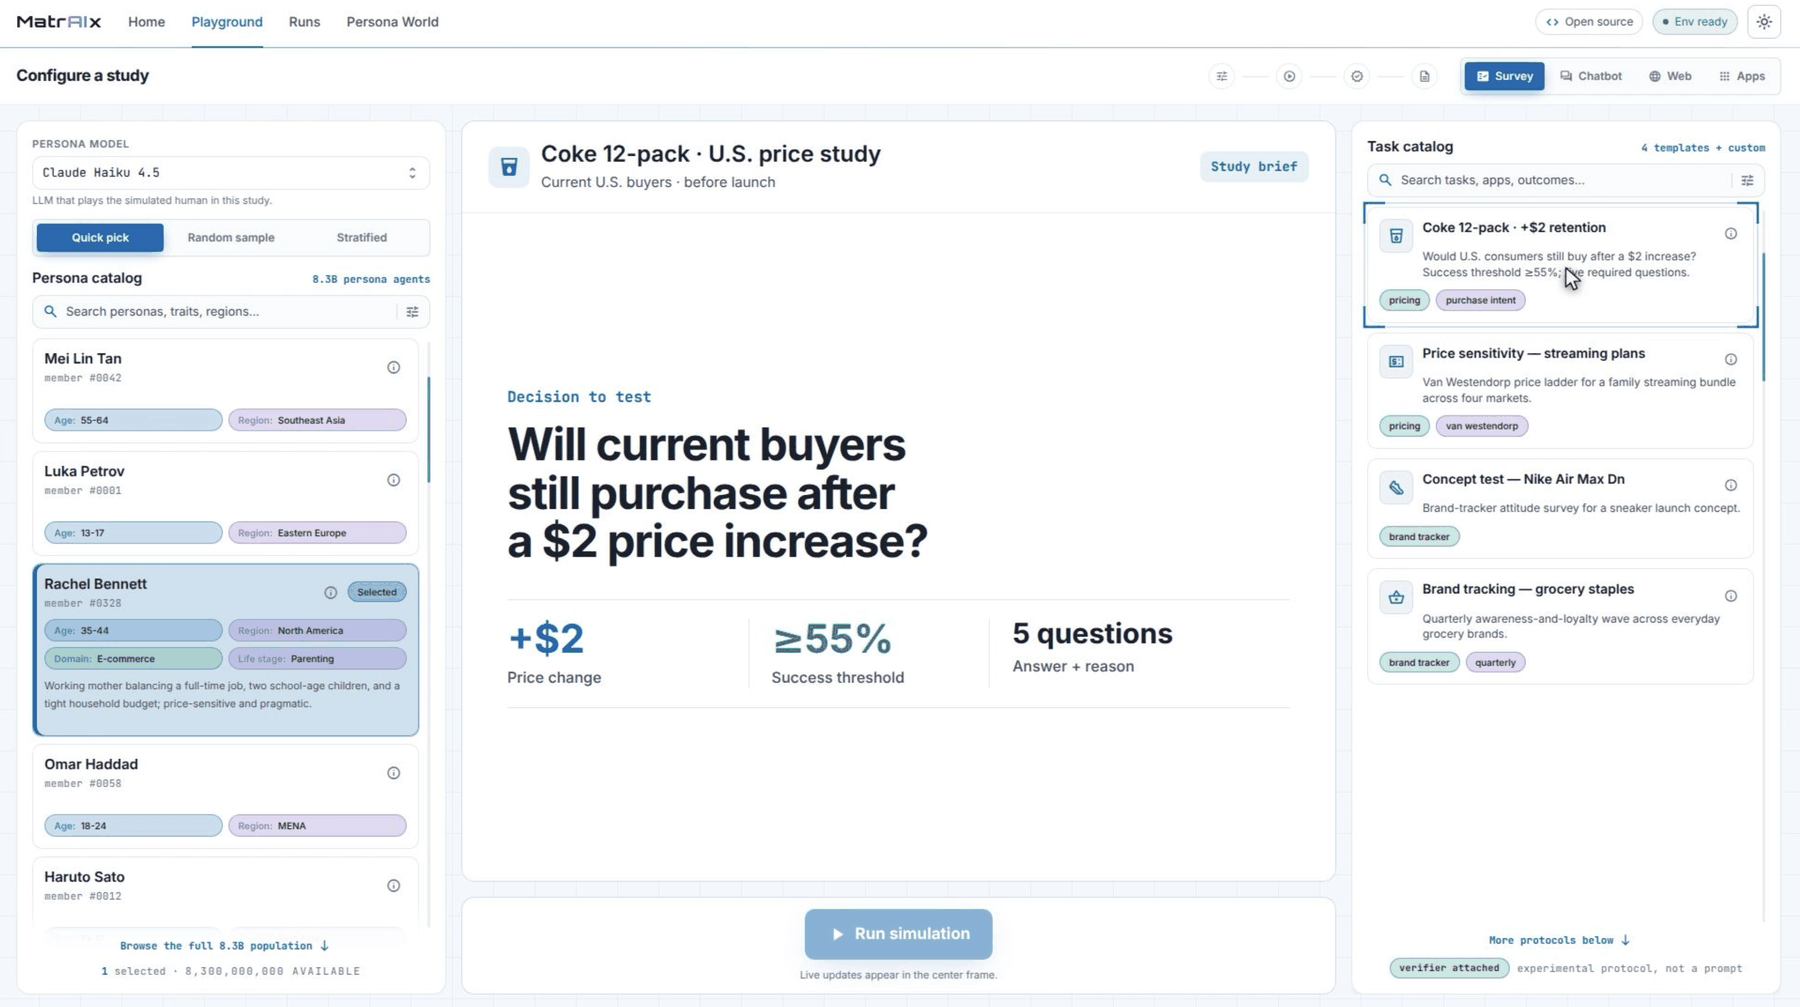
Simulating the World with 8.3 Billion PersonasThe MatrAIx technical report for a general audience: the persona population, the four study environments, and what the validation showed.
↗
PublicationJul 29, 2026
From Personas to Simulated Users: When Is an AI-Generated User Fit for Purpose?A fitness-for-purpose framework for deciding what persona-conditioned user simulations can and cannot show.
↗
PublicationJul 26, 2026
Position: Synthetic Persona Needs Explicit Grounding and Standardized ReportingExplicit grounding and standardized reporting for credible persona-based simulation claims.
↗
PublicationJul 26, 2026
PersonaEval: Persona-Based User Simulation for Evaluating Interactive ApplicationsA plug-and-play persona evaluation workflow for surveys, chatbots, and web applications.
↗
PublicationJul 26, 2026
MicroVerse: An Instrument for Measuring Self-Authored Identity Drift in Long-Horizon Multi-Agent Language-Model SimulationsMeasuring self-authored identity drift in long-horizon multi-agent simulations.
↗
PositionJul 20, 2026
To Simulate a User, You Should Make Your LLM DumberA frontier model is the right start for a human simulation and the wrong end; turning capability down to match a real person is its own research problem.
↗
PublicationJul 18, 2026
LLM-as-a-Developer: Evaluating 51 Agent FrameworksLLM-as-a-Developer: simulate the developer as the user of an agent framework to measure usability and effectiveness at ecosystem scale.
↗
PublicationJul 12, 2026
Measuring Persona Drift in Long-Horizon Agent SimulationsMeasuring and correcting persona drift in long-horizon agent interactions.
↗
AnalysisJul 3, 2026
The Cost of Synthetic-User Evaluation: Five Comparative EstimatesHuman cost, AI inference, elapsed time, and validity across five evaluation modes.
↗
PositionJul 2, 2026
Giving Agents a “Soul”: Persona as the Missing Layer for AI and RoboticsWhy preference settings are not enough, and agents need a persona that remains coherent across tasks.
↗
PositionJul 1, 2026
Why Human Simulation Is the Next Step for AI AgentsAn evidence-backed case for personas, evaluation, population simulation, and individual digital twins.
↗

Have research or insights to share? We welcome community contributions.

Submit a post →